











Sitemap Generator
A free sitemap generator that crawls your site the way a search engine does, keeps only the pages that belong in search results, and tells you why it left every other URL out.
A domain works too: example.org starts at its homepage.
- robots.txtRead first, obeyed
- Your sitemapFound and compared
- CrawledUp to 500 pages, 3 at a time
- Decidednoindex, canonical, redirects
How to create a sitemap, step by step
Enter your home page above and select Generate sitemap. The sitemap crawler reads robots.txt, follows your links the way a search engine does, keeps only the pages that belong, and hands you a sitemap.xml to upload to your site's root.
A page belongs when it answers 200, is HTML, is not noindex, names itself as canonical and is not blocked by robots.txt. Every other URL lands in Left out with its reason, so you can tell a mistake from a choice.
Upload the file to the root, https://www.example.org/sitemap.xml: a sitemap may only list URLs in its own folder and below, so the root covers the whole site (Google). Then add a Sitemap: line to robots.txt and submit it in Google Search Console and Bing Webmaster Tools.
1Enter your home page
example.orgor paste a list of URLs2We crawl and decide
robots.txt 200499/500412 in the sitemap · 87 left out3Download the file
sitemap.xml93 KBXML, gzip, ZIP, TXT, HTML or CSV4Upload and submit
/sitemap.xmlSitemap: https://www.example.org/…the root · robots.txt · Search Console



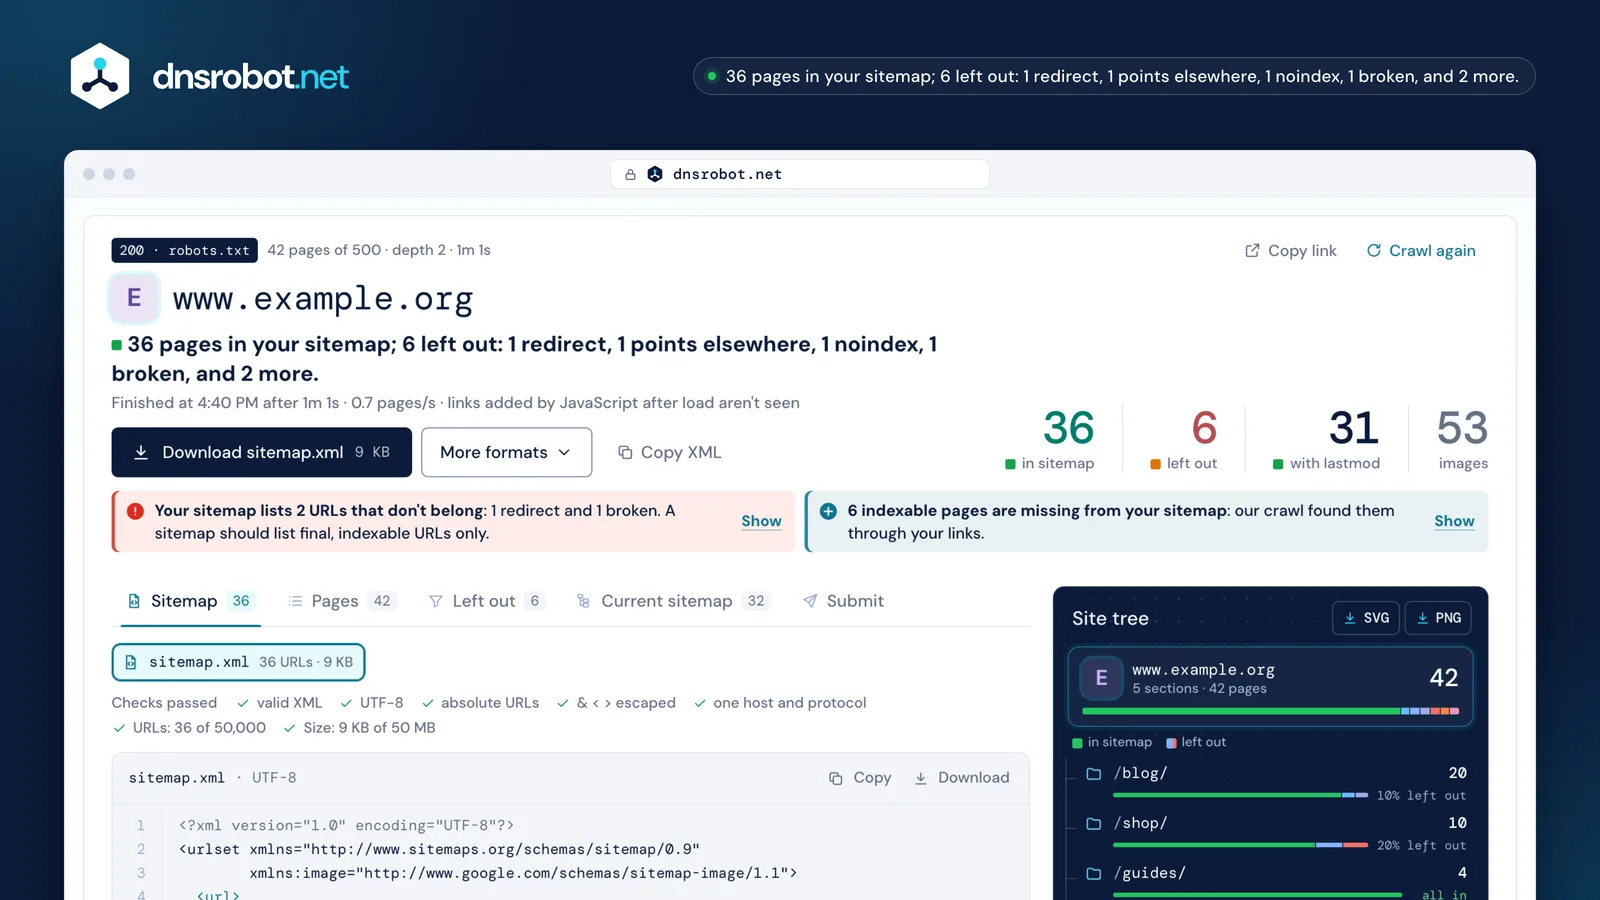
 The verdictHow many pages go in, how many are left out and why, in one sentence. The big numbers repeat it.Downloadsitemap.xml, or a ZIP with every file and the index when it is split; also .xml.gz, TXT, an HTML sitemap and a CSV of every crawled page.NoticesYour current sitemap's stale entries, the pages it misses, and where each lastmod date came from.The site treeEvery section with its page count and the share left out. Select a branch to filter the pages; download it as SVG or PNG.
What does an XML sitemap look like? A sitemap example
An XML sitemap is a UTF-8 file with one <url> entry per page. Only <urlset>, <url> and <loc> are required; everything else is optional. Here is a sitemap example, annotated line by line.
Each <loc> is a full, absolute URL that starts with the protocol and stays under 2,048 characters, with & written as & (sitemaps.org). <lastmod> is the date the page last changed, in W3C format such as 2026-09-14; a time is optional but needs a time zone.
The namespace stays on http://, even on an https site: it is a name for parsers, not an address anyone fetches. <changefreq> and <priority> are allowed, but Google and Bing ignore them.
<?xml version="1.0" encoding="UTF-8"?> 1 <urlset xmlns="http://www.sitemaps.org/schemas/sitemap/0.9"> 2 <url> <loc>https://www.example.org/</loc> 6 </url> <url> <loc>https://www.example.org/shop/?size=m&color=green</loc> 3 <lastmod>2026-09-14</lastmod> 4 <changefreq>weekly</changefreq> 5 <priority>0.8</priority> </url> </urlset>
- 1UTF-8, declared on the first line
- 2The namespace: http://, not https://
- 3An absolute URL, with & escaped as &
- 4The real change date, or no lastmod at all
- 5Ignored by Google and Bing
- 6No lastmod: a home page only gathers other pages
Which pages belong in a sitemap, and why are some left out?
The canonical URLs you want in search results, one per page: final URLs that answer 200, are indexable and are not blocked by robots.txt. Everything else is left out, with the reason written next to it.
A redirect, a noindex page or a URL whose canonical points elsewhere sends search engines a mixed message: the sitemap says “index this” while the page says otherwise. Do not name one URL in the sitemap and another in rel=canonical (Google), and Search Console reports sitemaps that list URLs robots.txt blocks.
Every URL in a sitemap is only a suggestion; Google still decides which pages are duplicates. That is why this generator shows the reason for each page it leaves out: a noindex you meant is fine, a noindex on your best product is not.
lastmod, changefreq and priority: what do search engines read?
Google and Bing ignore changefreq and priority. Both use lastmod, but only when it is accurate: a date that changes on every crawl teaches them to stop trusting it.
Google uses lastmod “if it is consistently and verifiably accurate”, and it should mark the last significant change — the main content, the structured data or the links — not a new copyright year (Google). A lastmod that keeps claiming fresh changes on old pages stops being trusted. Bing schedules crawls with lastmod and may disregard dates that are always today. Yandex still reads all three tags.
So this generator never writes today's date. It takes lastmod from the page's own data, in the order below, and leaves it out when there is none: leaving it out is fine for a home page or a category page that only gathers others.
| Tag | Bing | Yandex | |
|---|---|---|---|
| lastmod | uses it when accurate | uses it when accurate | reads it |
| changefreq | ignores it | ignores it | reads it |
| priority | ignores it | ignores it | reads it |
What “today” for every page looks like
412 entries, one date: a generation date, not a change date.
50,000 URLs, 50 MB and the sitemap index
One sitemap holds at most 50,000 URLs and 50 MB uncompressed. Past whichever limit you cross first, split the URLs into several files and list them in a sitemap index; then submit the index.
The limit counts the uncompressed file, even when you serve it as .xml.gz — gzip, not ZIP (sitemaps.org). An index may list up to 50,000 sitemaps, only files on its own site, in its own folder or deeper, and never another index. Naver Search Advisor refuses files over 10 MB, so choose the 10 MB limit in More options for a Korean site.
Language alternates (xhtml:link) do not count toward the 50,000. This generator splits automatically and, if you ask, by section: one file for the blog, one for the products.
4.4 MB
4.6 MB
4.5 MB
2.9 MB
Image and hreflang entries
A sitemap can also list each page's images and its versions in other languages, inside that page's own <url> entry.
Images use Google's image namespace, up to 1,000 per page; only <image:image> and <image:loc> still count, and caption, title, license and geo_location were retired in 2022.
For languages, each entry lists every version of the page, itself included, with xhtml:link and an hreflang code: an ISO 639-1 language with an optional ISO 3166-1 region, never a region alone. The links must go both ways or Google ignores them, so this generator writes a cluster only when every version links back, and shows the rest with the fault. x-default is optional, for visitors whose language you do not have.
<url>
  <loc>https://docs.example.net/de/guide/install/</loc>
  <image:image>
    <image:loc>https://docs.example.net/img/ui.png</image:loc>
  </image:image>
  <xhtml:link rel="alternate" hreflang="en"
    href="https://docs.example.net/en/guide/install/"/>
  <xhtml:link rel="alternate" hreflang="de"
    href="https://docs.example.net/de/guide/install/"/>
  <xhtml:link rel="alternate" hreflang="ja"
    href="https://docs.example.net/ja/guide/install/"/>
  <xhtml:link rel="alternate" hreflang="x-default"
    href="https://docs.example.net/en/guide/install/"/>
</url>
ja links to de, de does not link back: the cluster is not writtenimage entry up to 1,000 per page
How do I submit a sitemap to Google and Bing?
Add a Sitemap: line to robots.txt, which every crawler reads, and submit the file in Google Search Console and Bing Webmaster Tools. For new and changed pages, IndexNow tells Bing, Yandex, Naver and others at once.
Only a site's verified owners can submit in Search Console; anyone's robots.txt line works. Search Console does not follow redirects for a submitted sitemap, so submit its final address. Bing reads a sitemap as soon as it finds it, and then about once a day.
The old anonymous pings are gone: Bing switched off bing.com/ping on 13 May 2022, and Google announced on 26 June 2023 that its ping would stop working; it now answers 404. A tool that still “pings Google” does nothing.


XML vs HTML sitemaps (and visual sitemaps)
An XML sitemap is for crawlers, an HTML sitemap is a page of links for visitors, and a visual sitemap is a picture of the site's structure for planning. Only the XML one, or a TXT list, can be submitted to search engines.
An HTML sitemap still helps visitors and spreads links to deep pages, but it cannot stand in for the XML file. A plain-text sitemap is just URLs, one per line, in a file ending in .txt.
This generator makes all three from one crawl: sitemap.xml, an HTML sitemap to paste into a page, and the site tree. As a visual sitemap generator it costs nothing: the tree downloads as SVG or PNG, which visual sitemap services usually charge for.
XML sitemapfor search engines
<url>
  <loc>…/blog/</loc>
</url>
<url>
  <loc>…/product/</loc>
</url>
HTML sitemapfor visitors
Example Garden Co.
Garden journalRaised bed carePepper layoutShopDrip kit starterGrowing guidesVisual sitemapfor planning
Do you need a sitemap at all?
A small site whose pages all link to each other may not need one: Google puts the figure at about 500 pages or fewer. Large sites, new sites with few links from elsewhere, and sites with many images or videos benefit most.
Google's own starter guide calls a sitemap optional, and submitting one is a hint, not an order. It costs little, though, and the crawl that builds it shows things worth knowing: pages no link reaches, redirects your menus still point to, and sections that are mostly noindex.
may not need one
about 500 pages or fewer, well linked
benefits most
- large sites
- new sites, few links from elsewhere
- many images or videos
- 5 pages only the sitemap reaches
Sitemap errors in Search Console, and how to fix them
Most Search Console sitemap errors come down to a URL the sitemap may not list, a character that is not escaped, a date without a time zone, or a file over the limits. Each case below shows the line that causes it.
URL not allowed
sitemap: https://www.example.org/sitemap.xml
<loc>http://example.org/about/</loc>
Parsing error
<loc>https://www.example.org/search?q=soil&page=2</loc>
Invalid date
<lastmod>2026-09-14T08:30:00</lastmod>
→ 2026-09-14T08:30:00+00:00
Unsupported format
<urlset xmlns=“http://www.sitemaps.org/schemas/sitemap/.9”>
Too many URLs
<url> × 50,001
Sitemap contains urls which are blocked by robots.txt
robots.txt: Disallow: /search/
<loc>https://www.example.org/search/tomato/</loc>
Also: Couldn't fetch (blocked, 404, a server error, a manual action or low crawl demand), Compression error (re-gzip it) and Incomplete URL (each file in an index needs its full URL).
Can AI create a sitemap?
AI can sketch a site's structure for planning, but a sitemap is a list of facts about live URLs: which ones answer 200, which are noindex, which redirect. Only fetching each URL tells you that.
A model asked for the sitemap of an existing site guesses URLs from patterns. It cannot see that a product page now answers 404, that a tag archive is noindex or that an old post redirects, and every such URL in the file is one Search Console may report. Use AI for the plan, then crawl for the file.
Sources
- sitemaps.org protocol and its FAQ: the format, the 50,000 / 50 MB limits, the index, text sitemaps
- Google Search Central: build a sitemap, large sitemaps, localized versions, image sitemaps, lastmod and the retired ping and the Sitemaps report errors
- Bing: sitemaps in AI-powered search (2025), the lastmod tag (2023) and the removed ping (2022)
- Yandex: sitemap, Naver Search Advisor: feeds and IndexNow
- RFC 9309, the robots.txt standard this crawler follows
| URL | Guessed | Crawled |
|---|---|---|
| /blog/raised-care/ | include | In sitemap200 |
| /product/fern-varieties/ | include | 4xx404 |
| /tag/native-bed/ | include | noindexmeta |
| /2019/07/raised-care/ | include | Redirect301 → /blog/raised-care/ |
| /blog/pollinator-kit/amp/ | include | Canonical elsewhere→ /blog/pollinator-kit/ |
Sitemap generator FAQ
Is this XML sitemap generator free?
Why are some of my pages missing from the sitemap?
Where do I put the sitemap.xml file?
How many URLs can one sitemap have?
Does Google use priority and changefreq?
Why do some pages get no lastmod date?
Should a sitemap include redirects or noindex pages?
How do I submit my sitemap to Google?
My CMS already makes a sitemap. Do I need this one?
Does this sitemap crawler obey robots.txt?
Can it crawl a site built with JavaScript?
What is IndexNow, and do I still need a sitemap with it?
Missing something?Suggest a feature or a new tool
More crawling and SEO tools
Link Analyzer
Analyze all links on a webpage with dofollow/nofollow detection and HTTP status checking
Redirect Checker
Follow every redirect hop by hop: 301/302 chains, timing and bulk checks
HTTP Header Checker
Response headers exactly as sent, with a Mozilla Observatory security grade
Website Down Checker
Is it down for everyone or just you? Check any site from 11 places and your own connection, with a live screenshot
Subdomain Finder
Discover all subdomains of any domain
CMS Detector
What CMS, theme, plugins and technologies a website uses, with the proof for each